Просмотр новости
Найдите то, что Вас интересует
 Спутники
 РН
 SpaceX
 Роскосмос
 NASA
СпутникиРНSpaceXРоскосмосNASA Learn how to reduce AI workflow latency with production patterns for latency optimization: model routing, caching, parallel execution, timeouts, and budgets.
September 19, 2026 ∙ 8 minutes read
A single model call can be fast, but production AI workflows stack calls until latency becomes unbearable. You can’t code your way out of it. You need a workflow platform like n8n, with built-in controls for parallel execution, timeouts, and caching. This guide to reducing AI workflow latency shows you how to put them to work.
💡
n8n is a source-available AI-native workflow automation platform. It offers a visual canvas for building reliable automations. Users can design pre-defined steps and add non-deterministic AI capabilities into the mix. In this article, we provide examples relevant to n8n, but most of the concepts can also be applied to other platforms, whether they are visual no-code tools or various SDKs.
Total latency in an agentic system can be broken into three layers:
Each layer requires a different fix. Swapping models does nothing for a workflow that spends four seconds on three sequential API calls. And parallelizing those API calls won’t fix a workflow that has a bottleneck from running worker nodes across disparate availability zones. You need to identify where the lag is happening and address it directly.
The token lifecycle: Prefill, decoding, and Time to First TokenA large language model (LLM) request runs in two phases:
One important metric an engineer can track for interactive workflows is the amount of time a model takes to generate and deliver the first piece of text after you send a prompt, known as Time to First Token (TTFT). A low TTFT is typically anything under 200 to 500 milliseconds. If the TFFT is a second or longer (for a non-reasoning LLM), it may signal heavy server traffic or overloaded computer memory.
💡
Note that the TTFT metric applies only to interactive workflows, where the user can actually see the LLM’s response in real time. Various automations do not stream the LLM’s output directly to the user and only display the final output.
Tool calls can take multiple seconds. Every retrieval step and API lookup combines network round-trip time (RTT) with the target system’s processing time. If independent calls run sequentially, their latencies add up. For example, three calls that take 800 ms each and run sequentially take 2.4 seconds to complete. If you parallelize those calls, it takes about 800 milliseconds (not including any orchestration overhead).
💡
Most recent LLMs support parallel tool calling. If your workflow supports independent tool calls, you can prompt the model to use this feature in order to improve the workflow performance.
Orchestration overhead typically causes shorter delays, which makes it easy to overlook. A 100 millisecond delay between steps looks harmless. But when you multiply it across retrieval, inference, and post-processing, you can find seconds of latency visible to the user.
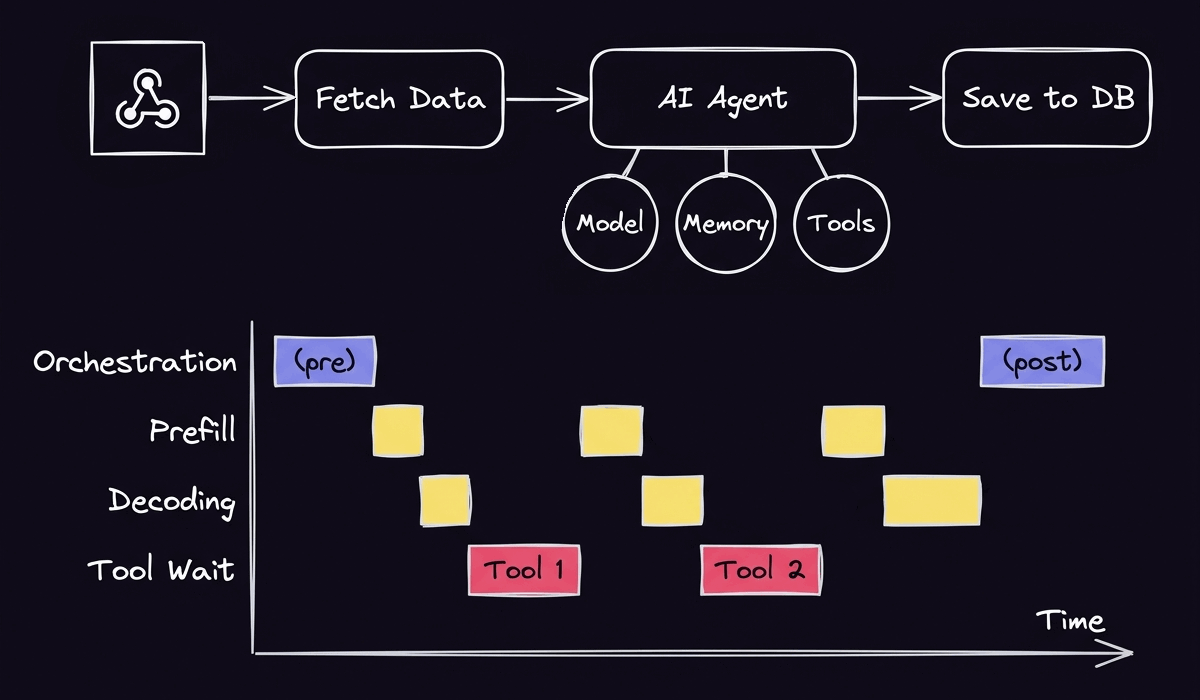 In the most basic case, a total AI workflow delay consists of pre-AI / post-AI orchestration steps (blue), LLM prefill / decode times (yellow) and the Tool call delays (red)Latency budgets
A latency budget is the total allowable response time that an engineering team or product manager sets for an agentic workflow to respond. Workflow designers can divide the total budget among specific steps, such as data retrieval or network hops.
But first, make sure latency is the problem in your system. You don’t want to spend weeks optimizing response time when users actually need better accuracy or retrieval.
If you’ve built your workflow in n8n, you can view executions to figure out where a run spent its time. Once you confirm latency is the problem in your system, analyze the following factors.
Time to Complete Response (TTCR). Understanding the total amount of time a model takes to process the prompt, complete its reasoning, and finish delivering a response is important for latency optimization.
TTFT. The TTFT has an outsized impact on the user’s perception of latency in the system. Try to keep it between 300 and 500 milliseconds or lower.
Output Tokens per Second (OTPS). The speed at which a model generates new text after its initial response impacts the user experience and how efficiently a complex workflow can complete background tasks. Adding the OTPS and TTFT together create the TTCR.
Workflow type. Real-time or interactive workflows, such as a chat agent or support bot, need a faster response time than a background workflow, such as a data sync.
Your exact needs may vary, but here are some example end-to-end latency budgets per workflow type.
When you build the orchestration layer yourself, you can own a scheduler and execution store forever. n8n lets you configure patterns like parallel execution, timeouts, and caching directly in the workflow, reducing the need for custom orchestration code. Here’s how.
Run parallel tool calls within an AI Agent stepWhen an agent needs to run two independent lookups, the model can request both in the same turn and the AI Agent node fires them together.
Let’s say an agent needs to look up two currency exchange rates before running a calculation. The model can run both exchange-rate lookups in parallel. The calculator, which is dependent on their results, waits to run the calculations in sequence.
For more complex architectures, the AI Agent Tool node can delegate work to specialist agents.
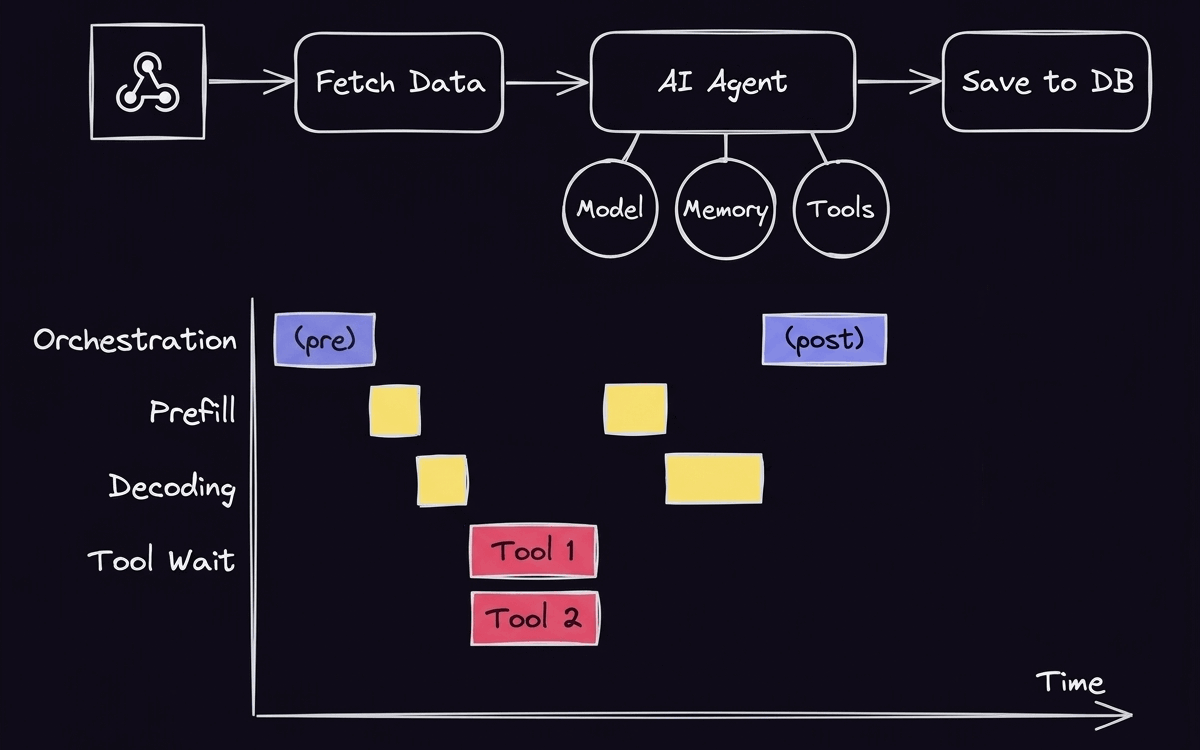 When the Tools are called in parallel, you save time not only by stacking the Tool execution timing, but also by reducing the amount of LLM calls (since LLM is called one time after both tool executions are finished)
See how parallel tool calls work in the AI Agent node
Fail fast with timeouts, retry limits, and guardrailsA hung API call is one of the most expensive kinds of latency because nothing downstream can start until it resolves.
Set a hard timeout on external calls. The HTTP Request node supports a timeout so a slow endpoint can fail at a set time and deploy an intentional fallback instead of stalling the entire workflow indefinitely.
A retry can improve reliability for transient failures, but it also increases latency. If an API call normally takes one second and the system runs three retries with a three-second timeout each run, a failure can consume much more of the workflow’s latency budget than a single request.
Use n8n to handle rate limits for retries at either the node or workflow level. If you want to use bounded retries on your node, click on it and open its Settings. Enable the Retry On Fail toggle, and set the maximum number of tries. If you want to cap the entire execution, configure the workflow settings to time out after a certain amount of time passes.
The Guardrails node can help catch bad inputs that send the agent down a long, useless path. You can configure it to detect violations, such as URLS, regular expressions, secret keys, personally identifiable information, and sanitize them with placeholders. Or you can use a full set of guardrails that send any violations to the Fail branch.
Isolate slow operations with sub-workflowsSome steps are slow for reasons you can't fix. If a vendor API takes eight seconds, moving the call into another node won’t make the vendor faster. But a sub-workflow can improve the architecture around that slow operation.
Break workflows into smaller parts in n8n with the Execute Sub-workflow Trigger node. This lets you give the slow step its own timeout, retry, and concurrency settings. You can also control whether the parent workflow waits for it to complete.
Scale execution with concurrency and queue modeWhat happens when 40 executions land at once and your instance runs them all? Everything slows down, and a throughput problem starts looking like a latency problem.
n8n limits the number of concurrent executions for Cloud instances depending on your plan. If you’re self-hosting n8n, you can control concurrency to cap how many production executions run at once. And if you enable queue mode, the main instance handles triggers and webhooks and hands each execution through Redis, where a pool of workers picks up the job. This lets you scale throughput as you add workers.
Get started in 10 minutes with n8n Cloud — free to try.
Two variables drive inference latency: The model you pick sets how fast each token comes out, and the length of the answer sets how many you wait for. LLM latency optimization starts with choosing the right model and minimizing unnecessary output.
Route tasks to right-sized modelsClassification and short extraction steps run well on a small model. Smaller models generate tokens faster because each token uses less compute, so swapping a large dense 70B model for a smaller Mixture of Experts (MoE) saves hundreds of milliseconds per query. Reserve the large model (especially the one with built-in reasoning) for multi-step automations.
Cut output tokens before input tokensGenerated output is often the easiest inference cost to control because decoding is sequential. OpenAI’s latency optimization guidelines suggest the relationship between output and latency is close to linear. If you cut 50% of your output tokens, you can cut about 50% of your latency.
To cut output tokens, start capping the model’s response. Set a maximum output length, ask for structured output with short field names, and tell the model to answer in a set number of words.
Prompt caching and semantic cachingThe model provider generally controls prompt caching. When a request repeatedly shares a cacheable prefix, the provider can avoid recomputing some of the input processing. This can reduce input-processing latency but doesn’t eliminate the decoding phase — the model still runs end to end.
Semantic caching can avoid inference entirely for new requests that are similar to existing ones.
For example, one user asks “What’s your return window?” Another user asks “How long do I have to send something back?” The questions are asking for the same information in different words, so the semantic cache can retrieve a previous answer instead of prompting the model again.
In n8n, the Redis Vector Store enables zero-inference cache hits for repeated queries, not just exact and semantic caching.
The key to reducing AI workflow latency is to optimize in the right order. Start by measuring where you’re losing time in model inference, tool calls, or orchestration overhead. Get the workflow patterns right, then clean up the model-level basics.
With n8n, you can measure executions and apply latency patterns directly into your workflows.
Try n8n today and start building faster AI workflows without adding custom orchestration code.
| # | Наименование новости | Тональность | Информативность | Дата публикации |
|---|---|---|---|---|
| 1 | Process Orchestration: Execution Models, Observability, and Production Challenges | 0 | 7.16 | 11-09-2026 |
| 2 | Reflection Pattern: AI Agents Self-Correct in Production | 0 | 14.35 | 11-09-2026 |
| 3 | Prompt Testing Frameworks for Production AI Workflows | 0 | 8.04 | 21-09-2026 |
| 4 | AI Agent Reliability: Debug, Evaluate, and Monitor in Production | 0 | 5.74 | 08-09-2026 |
| 5 | Autonomous AI Agents: Architecture and Risk Mitigation | 0 | 6.94 | 10-09-2026 |
| 6 | How the Transactional Outbox Pattern Guarantees Event Delivery | 0 | 8.88 | 19-09-2026 |
| 7 | API Rate Limiting for More Reliable Workflows | 0 | 5.99 | 18-09-2026 |
| 8 | Telcos need a revamp to make the most of AI – report | 0 | 13.05 | 18-09-2026 |
| 9 | How To Build Reliable Workflows With API Idempotency | 0 | 8.23 | 03-09-2026 |
| 10 | AI Agents Are About to Flood the Workforce. No One’s Ready for It | 0 | 9.37 | 28-09-2026 |