Просмотр новости
Найдите то, что Вас интересует
 Спутники
 РН
 SpaceX
 Роскосмос
 NASA
СпутникиРНSpaceXРоскосмосNASAWeb scraping vs API: learn the key differences and why API-based social aggregation is better for reliable social media data and widgets.
At EmbedSocial, I see the same pattern again and again: Brands are surrounded by customer proof, yet their websites still rely on stale testimonials, manual screenshots, or outdated social media feeds that no longer reflect what customers are saying today.
That is why the web scraping vs API debate matters so much in my world.
On paper, both methods can collect online data. In practice, they create very different outcomes when your goal is to publish fresh reviews, UGC, and social proof on a live website.
I have seen teams start with a quick workaround, only to discover that the real challenge is not collecting user-generated content once.
The real challenge is aggregating and embedding social media posts reliably, moderating them properly, and using them to become more trustworthy.
Well, below, I explain what is web scraping, show how web scraping works, break down the difference between web scraping and API, and explain why API-based social aggregation like EmbedSocial’s is usually the better long-term model for brands.
Before diving in, here’s the rundown:
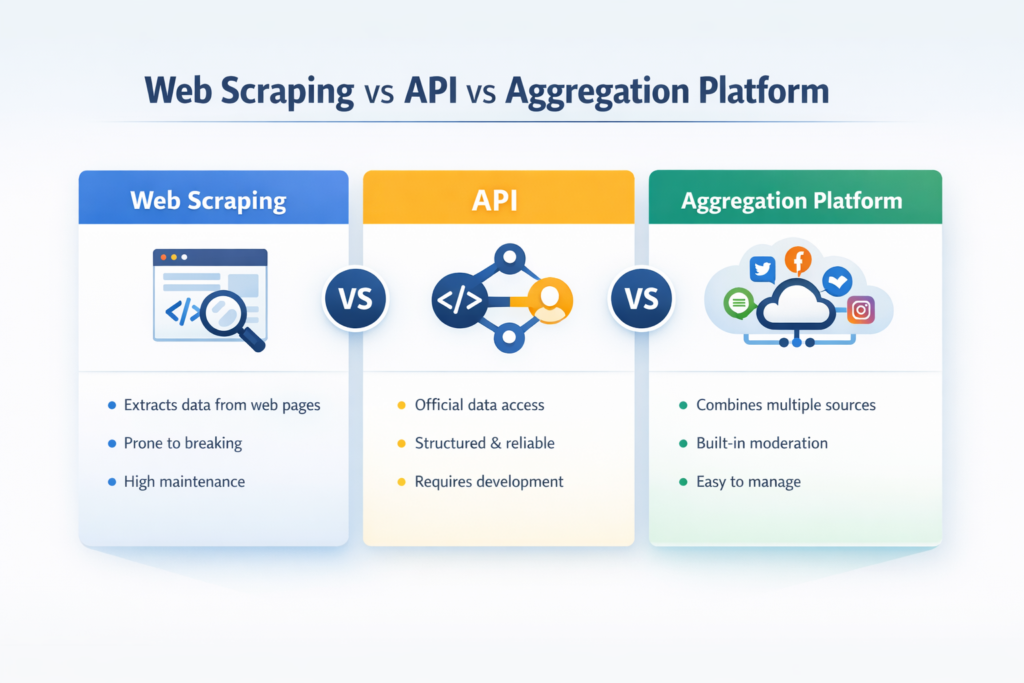
If someone asks me what is web scraping, my simplest answer is this:
It’s the process of extracting visible information from a webpage and converting it into structured data. A scraper visits a page, reads what is displayed in the HTML or rendered interface, identifies the elements it wants, and saves that information in a more usable format.
‘Web scraping’ definition
That information can include review text, usernames, captions, ratings, product details, image URLs, timestamps, or other public-facing data access.
This is why scraping is popular in research-heavy workflows. Businesses can extract data for social listening use cases, such as competitor tracking, public review analysis, price monitoring, and, in some cases, web scraping social media data.
I want to be fair here: scraping is not inherently wrong or useless.
It can be practical when no suitable API exists, or when the goal is internal analysis rather than customer-facing publishing.
The problem starts when teams assume a method built for extraction is automatically good for ongoing website content operations.
From my experience, that is where things begin to break.
How web scraping works?Most explanations of how web scraping works stay too abstract. I think it is much clearer when you look at it as a step-by-step process:
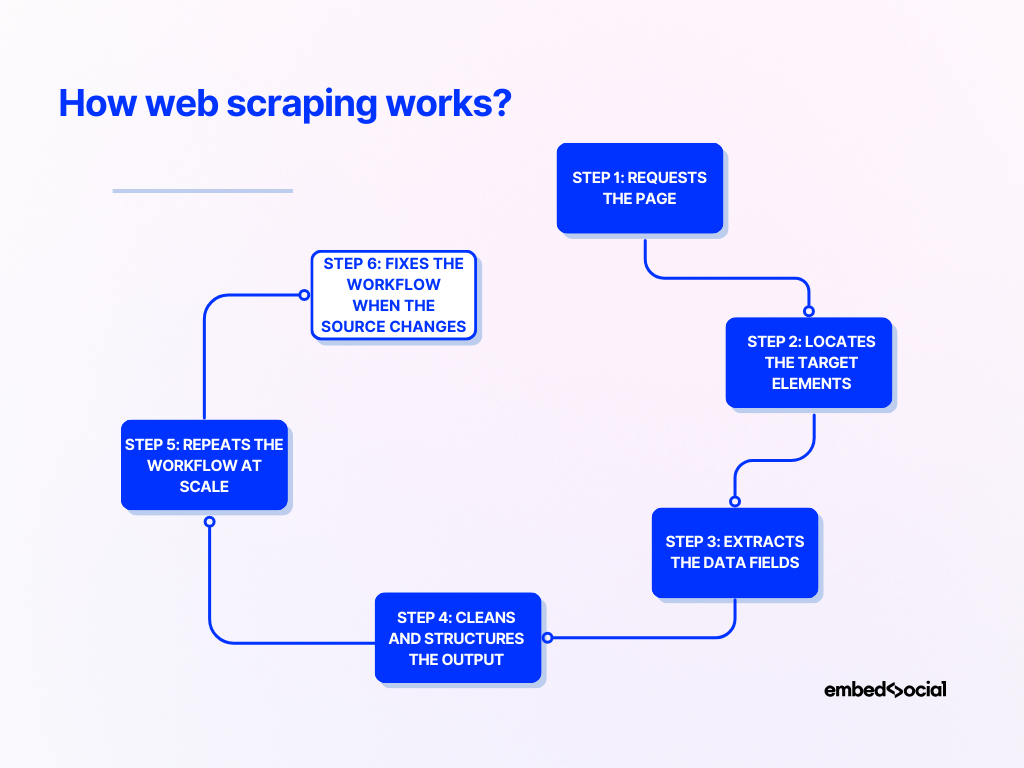
A scraper first sends a request to the target website and retrieves the page content.
In simple cases, that means downloading raw HTML. In harder cases, it may need to render JavaScript or simulate a browser session.
Step 2: Locates the target elementsNext, the scraper scans the page structure for the data it needs.
It might rely on CSS selectors, class names, element IDs, XPath paths, or repeated components to find the right content blocks.
Once the target elements are located, the scraper pulls out the useful fields.
That may include captions, ratings, author names, hashtags, media links, dates, review text, or other visible attributes.
Step 4: Cleans and structures the outputScraped data is often messy.
So the next step is to normalize dates, remove extra characters, reshape fields, and convert everything into a structured format like JSON or CSV.
Step 5: Repeats the workflow at scaleIf the goal is ongoing collection, the scraper runs repeatedly across multiple pages, profiles, feeds, or source URLs. This is where the maintenance burden starts to show up.
Step 6: Fixes the workflow when the source changesA scraper depends on page structure. If the source platform changes how captions, thumbnails, or page elements load, the workflow may fail. That failure may be minor in an internal report, but it is much more serious when the result appears on a public website.
In such a case, you have to adjust the scraper.
What is an API?Real-life example:
I have seen a social content feed work perfectly in testing, then quietly degrade after a platform changed how media cards were rendered. The team did not just lose data quality. They ended up with a broken website experience.
An API, or application programming interface, is an official way for one system to request data from another in a structured format.
‘API’ definition
That definition sounds technical, but the practical difference is simple.
With scraping, you read what appears on the page. With an API, you request data through a channel built for software access.
Instead of parsing visible front-end content, you receive structured data directly from defined endpoints, often in JSON.
That usually makes the workflow easier to maintain.
The data is cleaner, the structure is more predictable, and the integration is less dependent on how a page looks in the browser.
Of course, APIs are not perfect. They can have limits, approvals, quotas, and provider-controlled rules about what data is available.
But for recurring workflows, especially ones tied to a live website, APIs are usually a much stronger operational foundation. The same structured access is what a social listening API uses to collect mentions and hashtags.
Web scraping vs API: the key differences at a glanceWhen people search API vs web scraping or web scraping vs. API, they usually want a fast, practical comparison. This is the framework I use most often:
Web scraping
API
Data source
Visible page content or rendered interface
Official structured endpoint
Data format
Raw or semi-structured
Structured and easier to integrate
Reliability
Vulnerable to layout and rendering changes
Usually more stable
Maintenance
Higher
Lower
Compliance clarity
Less predictable
Usually clearer
Flexibility
High for public pages
Limited to what the provider exposes
Best fit
Research, monitoring, one-off extraction
Repeatable integrations and publishing workflows
Fit for social proof on websites
Often fragile
Usually far better
The real difference between web scraping and API is not just where the data comes from. It’s also how much effort comes after collection to keep the system usable, stable, and publish-ready.
Pros & cons of web scrapingBecause one of the main supporting keywords here is pros and cons of web scraping, I want to show that tradeoff clearly rather than oversimplify it.
Web scraping pros
Web scraping cons
Can collect public data even when no API exists
Breaks when layouts or rendering change
Highly flexible and customizable
Requires ongoing maintenance
Useful for monitoring, research, and social listening
Can face anti-bot systems and blocking
Less dependent on provider API availability
Data formatting is often inconsistent
Helpful for lightweight experiments
Can create policy or governance risk depending on use
Can capture visible fields APIs may not expose
Weak fit for polished, customer-facing website experiences
My honest view is that scraping is often strongest when the output is internal. Once the output becomes public-facing and brand-sensitive, the weaknesses become evident.
Advantages of using APIsIf I had to summarize the main advantages of using APIs for this use case:
In short, APIs do not just help you collect data. They help you build a system around that data. Data extraction becomes a reliable process that provides structured data access.
Plus, APIs allow you to target website pages to get specific data instead of scraping everything from said pages and then sifting through the contents.
Most generic web scraping vs API articles treat all online data as if it belongs in the same bucket. From my experience, that is where the analysis gets too shallow.
Social media content stops being ‘just data’ the moment it appears on a homepage, product page, or review widget. At that point, it becomes trust-building content.
General web data use case
Social media data use case
Often used for internal analysis
Often used for customer-facing proof
Minor formatting issues may be acceptable
Formatting directly affects perception
A temporary gap may be inconvenient
A broken feed can damage trust
Usually focused on retrieval
Requires retrieval, moderation, and publishing
Often lives in dashboards or reports
Lives on websites, widgets, and conversion pages
Lower brand-risk if internal only
Higher brand-risk because customers see it
That is why I separate these use cases so strongly. A spreadsheet can tolerate messy output. A live UGC widget cannot. You don’t just extract data from web pages, you re-implement that data in trust-building, live website widgets that update automatically.
The appeal of web scraping social media data is obvious at first. Public content looks accessible, setup can feel fast, and teams may believe they have found a shortcut.
In practice, the model starts to break down in predictable ways:
Front-end changes create fragilitySocial platforms change often.
A feed that depends on visible page structure can stop working when a caption loads differently, a media element is restructured, or the platform changes how the interface is rendered. To reduce the risk of getting blocked, teams often use residential proxies for web scraping to rotate IP addresses and mimic genuine user traffic patterns.
Formatting quality becomes hard to controlPro tip:
Never build a customer-facing feed on top of page layout assumptions alone. If a platform changes how captions, cards, or media render, your feed can break overnight. which is why official API access is usually the safer foundation for anything public-facing.
Even when a scraper technically works, the output may not be fit for publishing.
I have seen scraped social content come through with missing captions, poor media rendering, uneven card layouts, and incomplete attribution.
Moderation becomes a manual burdenPro tip:
A feed that “technically works” is not the same as a feed that is publish-ready. Before content goes live, make sure you can reliably control captions, media quality, attribution, card consistency, and fallback behavior across every layout.
Once content is collected, somebody still has to decide what should actually go live.
That means UGC management like filtering spam, removing irrelevant posts, excluding low-quality content, and checking whether the final result still feels on-brand.
Scale multiplies the maintenance costPro tip:
Content collection is only half the job. The real operational win comes from having built-in UGC management workflows for filtering spam, removing irrelevant posts, surfacing the best content, and keeping every widget aligned with your brand standards.
One experimental feed is manageable.
Multiple feeds across product pages, campaigns, and client websites create a very different maintenance burden. Large scale data collection needs API access. If you want to obtain data, reliable data at scale, you need direct accesse to the data availability.
Governance gets harder to managePro tip:
One experimental feed might be manageable with scraping, but large-scale data collection is a different game. Once you need reliable content across multiple pages, campaigns, or client sites, direct access to stable data availability matters far more than short-term setup speed.
Depending on the platform, content type, and use case, scraping can raise extra questions around terms, privacy, access, and brand risk.
For many teams, that uncertainty alone makes it a weak foundation for customer-facing proof.
Direct API vs aggregation API: what’s the difference?Pro tip:
If the content will influence trust or purchase decisions, the collection method should be judged by reliability and governance, not just by whether it can pull the data once.
This is the distinction most API vs web scraping articles miss. Many teams think the choice is simply between scraping and using an API.
In reality, the more useful comparison is between scraping, direct API integration, and a managed social media aggregator layer.
What you get
Main drawback
Best fit
Web scraping
Flexible access to visible public content
Fragile, maintenance-heavy, messy for publishing
Research, monitoring, experiments
Direct API integration
Official structured access to source data
You still have to build moderation, syncing, formatting, and publishing logic
Technical teams with development resources
Aggregation API or platform
Official access plus workflow, moderation, organization, and publishing tools
Less raw control than fully custom systems
Brands, marketers, agencies, e-commerce teams
Direct API access is powerful. But many teams underestimate what comes after connectivity. Once you have the data, you still need source management, moderation rules, transformation logic, refresh cycles, widget generation, layout control, and ongoing upkeep.
That is why I keep coming back to the same point: raw access is not the same as a working social proof pipeline. You need a social media aggregator like EmbedSocial.
When web scraping still makes sense?
I do not think a credible article on web scraping vs. API should pretend scraping has no place. It absolutely does. A good example is social listening.
If a team wants to monitor public conversations, explore visible discussions, or gather data for internal analysis, scraping can be practical and efficient.
Another example is niche public data collection.
Sometimes the needed information is public, but no useful API exists. In those cases, scraping may be the only realistic path to the data.
I also think scraping can make sense for lightweight internal experiments.
If the workflow is temporary, the team understands the fragility, and nothing customer-facing depends on it, the tradeoff may be acceptable.
But once the content becomes part of the public brand experience, I usually advise teams to raise the standard. That is where scraping often starts becoming a liability.
Why API-based social aggregation is the better long-term system for brands?This is where the business case gets much clearer. An API-based aggregation model is better for brands because it solves more than collection.
It helps manage the full lifecycle of the content after collection.
Take a growing e-commerce brand as an example.
It may want recent reviews on product pages, UGC on landing pages, and social proof on the homepage. Trying to maintain that through scattered workarounds creates drag very quickly. Centralized, API-based aggregation makes that system manageable.
A service business is another good example.
Replacing static testimonial screenshots with live review content can make the site feel more current, more believable, and more aligned with what customers are saying right now. Imagine a wall-of-love page on your website that updates automatically.
I also care about how much work a system creates behind the scenes. A good workflow reduces screenshotting, manual curation, repetitive developer tickets, and emergency fixes.
Example from my work at EmbedSocial:
I have seen businesses replace an outdated testimonial block with a live stream of recent Google reviews and social mentions. The result was not just fresher content. The site felt more active, more current, and more credible.
This is the part I know most directly from hands-on experience.
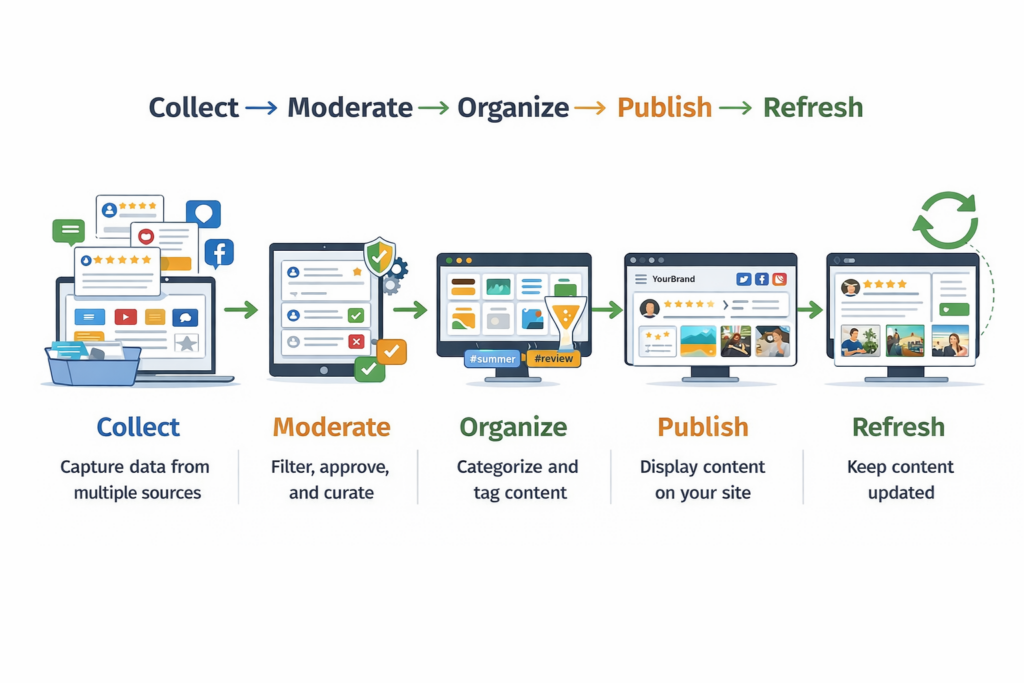
At EmbedSocial, the goal is not just to help brands collect content. It is to help them turn real customer content into something organized, moderated, and publish-ready.
Here’s a simple graphic covering the process of aggregating social media content:
And here are the steps you need to complete after creating your EmbedSocial account:
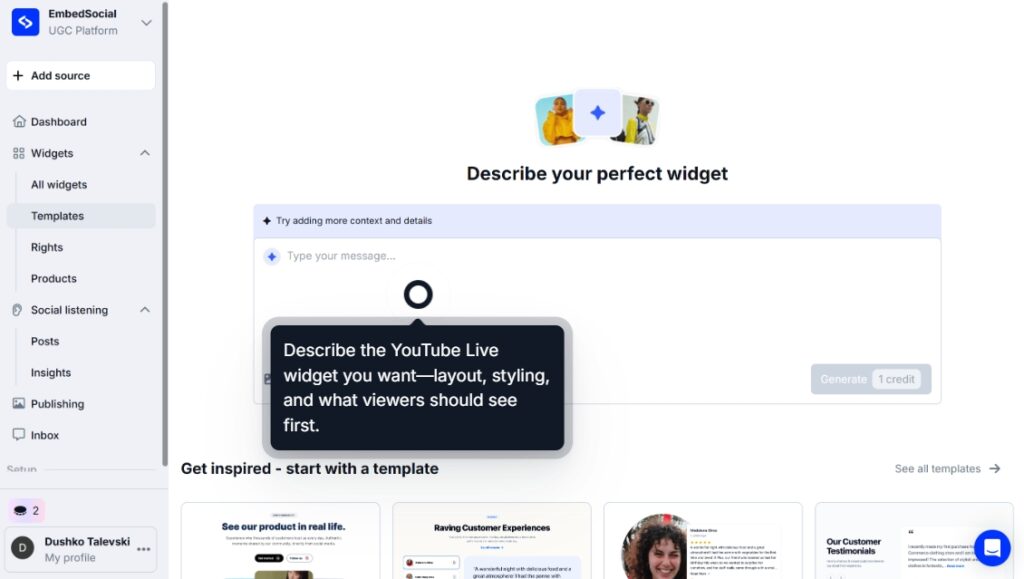
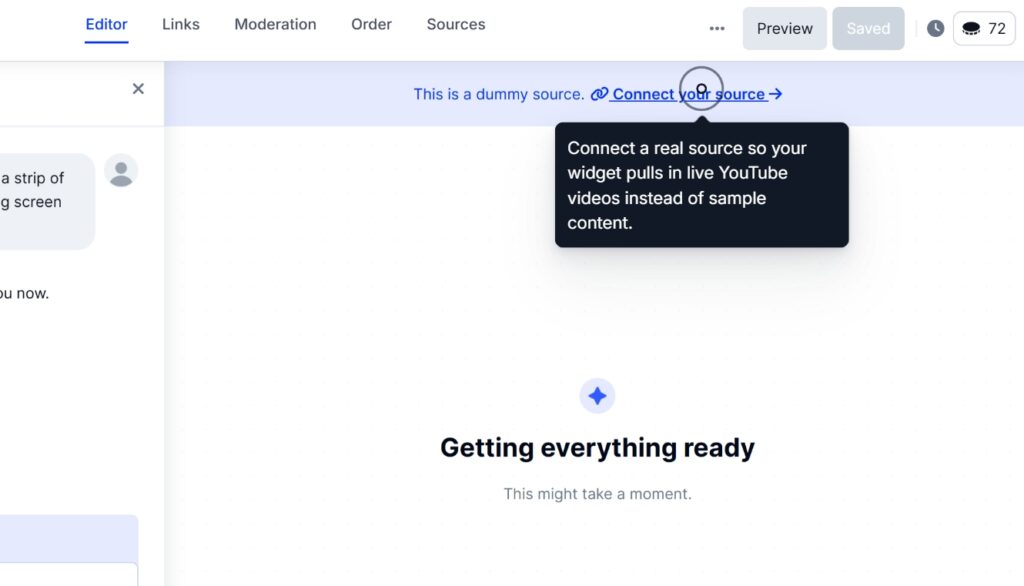
Step 1: Submit an AI widget design promptFirst, you have to prompt the AI widget editor to create your new social media widget:
Then, you have to connect to your social media to pull their content in EmbedSocial:
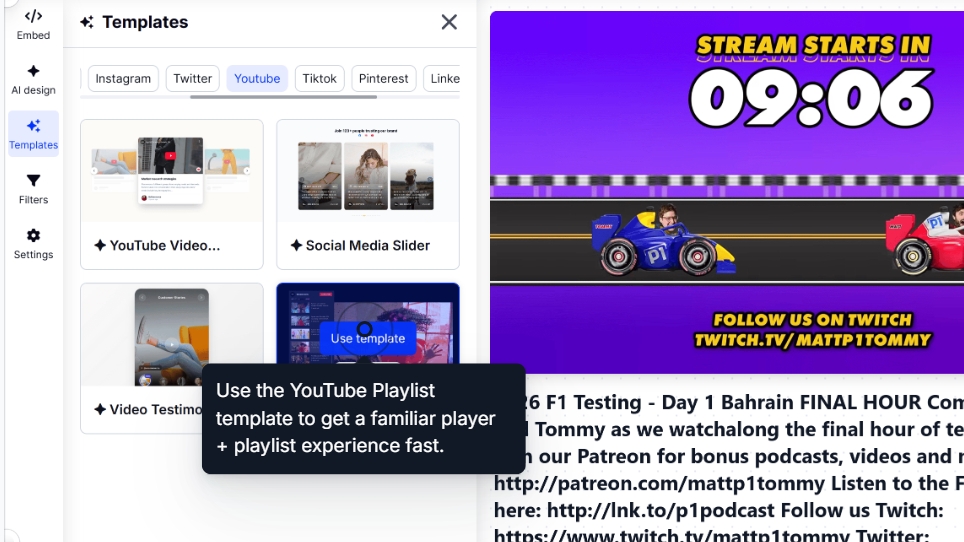
Then, you can select your widget template and further customize it via AI prompts:
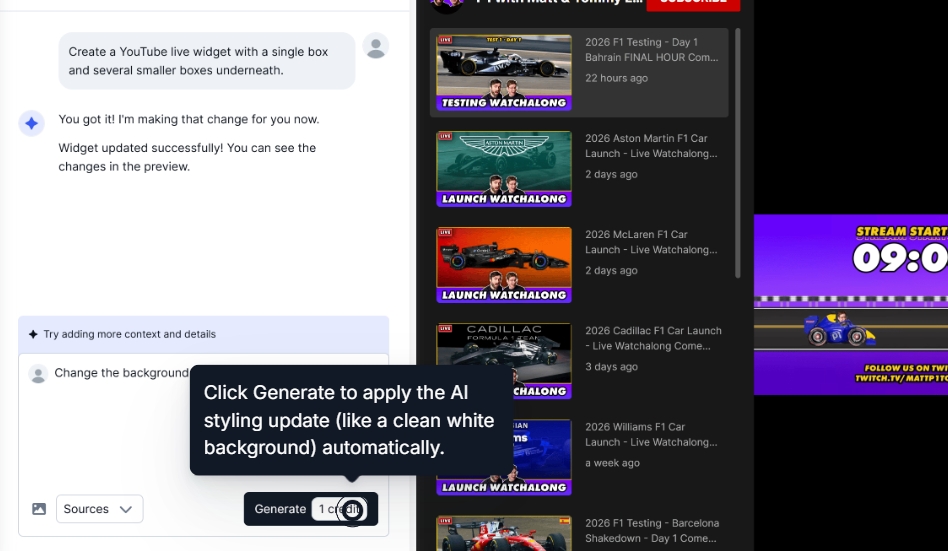
If you’re unhappy with the widget look, simply navigate to AI design and add further prompts:
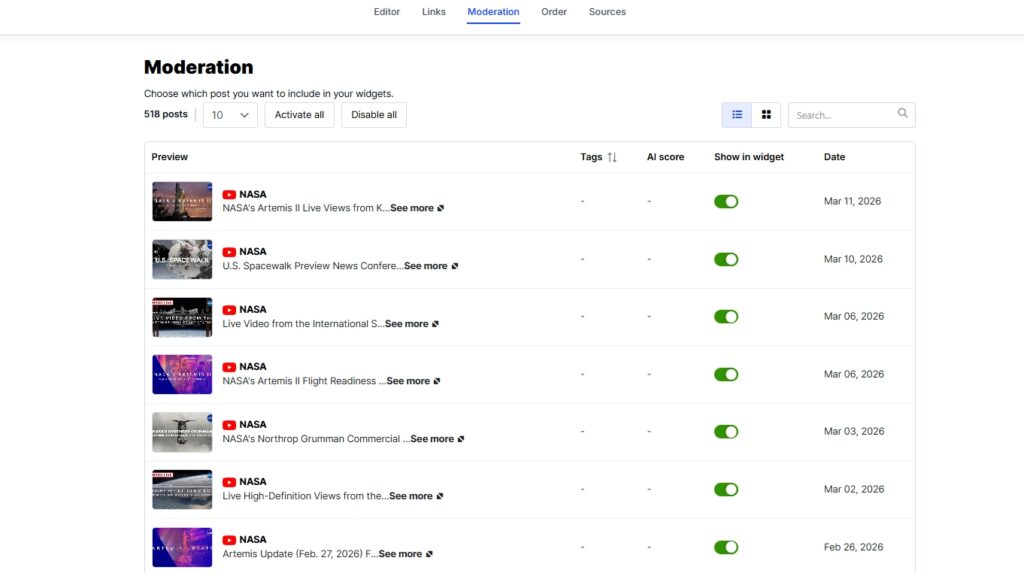
Head on over to the Moderation tab to select specific posts you want to showcase:
Once the widget or feed is ready, you need to copy its embeddable code via the Embed tab:
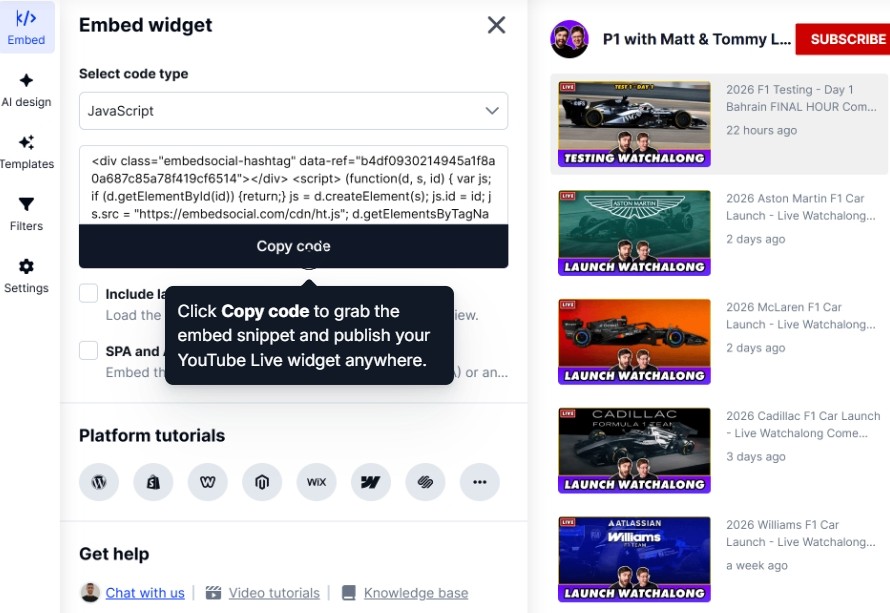
The last thing you need to do is navigate to your website builder and paste the widget code.
Here’s how that works across all popular website builders:
The reason web scraping vs API remains such a common question is simple: both methods can help collect online data. But for brands, that framing is still too narrow.
The better question is how to turn social media content into a stable, trustworthy, customer-facing experience that keeps the website fresh over time.
From my perspective, scraping still has a place in research, monitoring, and exploratory analysis. But when the goal is publishing social proof on a live website, an API-based aggregation workflow is usually the smarter long-term answer.
That approach gives you more than access.
It gives you structure, moderation, consistency, and a realistic path from scattered customer content to live website widgets that actually build trust.
| # | Наименование новости | Тональность | Информативность | Дата публикации |
|---|---|---|---|---|
| 1 | 10 Best Social Media Widgets for Websites (2026) | 0 | 13.31 | 31-03-2026 |
| 2 | Facebook Graph API: How to Get an Access Token and Use It | 0 | 3.43 | 29-09-2026 |
| 3 | How to Embed Testimonials on Website in 2026 [2 Methods + Tips] | 0 | 11.9 | 19-03-2026 |
| 4 | 15 Best Social Media Automation Tools for 2026 (by Category) | 0 | 12.96 | 23-06-2026 |
| 5 | 7 Shoppable AI Widgets for Shopify to Increase Conversions | 0 | 8.49 | 02-02-2026 |
| 6 | YouTube API Key: How to Get One and What It Really Costs | 0 | 7.27 | 28-09-2026 |
| 7 | How to Add Instagram Feed to Wix (and Keep It From Breaking) | 0 | 7.89 | 02-10-2026 |
| 8 | AI Agents vs Chatbots: Understanding Key Differences and Their Impact | 0 | 5.04 | 06-09-2026 |
| 9 | RAG vs Fine-Tuning: Which Should You Use for Your AI App? | 0 | 15.76 | 02-10-2026 |
| 10 | RAG vs Fine-Tuning: Choosing the Right Approach for Your AI Applications | 0 | 14.49 | 11-09-2026 |